 Jordan
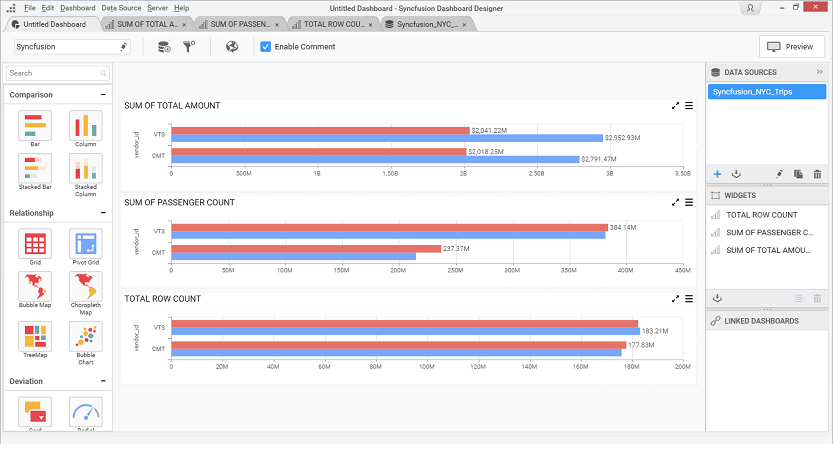
How long should it take to process 173 GB of data and then create a dashboard to make sense of it? Ten minutes? Three minutes? Two minutes? Those all sounded like reasonable estimates. We decided to put the Syncfusion Big Data and Dashboard Platforms to the test to see just how fast we could get it done.
30 seconds.
We have to admit, that’s faster than we expected. Here’s how we made it happen:
We used a data set of New York City taxi trips between 2009 and 2015. In total, this covered 1.1 billion individual taxi trips, giving us 1.1 billion records to play with. First we uploaded and processed the data with the Big Data Platform, and then we designed and displayed the results with the Dashboard Platform.
So what does it take to achieve these kind of speed results? And are they typical? And do you need enterprise-level hardware to make it happen?
The good news is you can get similar results using even the most basic hardware set up. This is the first time commodity hardware can do the heavy lifting, and it’s all because of the Syncfusion Big Data and Dashboard Platforms.
| Node types | Number of nodes | Machine specs |
| Name node running Syncfusion Big Data Platform | 2 | Azure VM instance typeD4 standardRAM28 GBHard disk400 GBCore8OSWindows Server 2012 |
| Data node running Syncfusion Big Data Platform | 3 | Azure VM instance typeD15 standardRAM140 GBHard disk1 TBCore20OSWindows Server 2012 |
The hardware configuration used in this test.

With Apache Spark 2.0 releasing soon, we decided to re-run our tests. The results were even better this time around:
| Query | Without tuning Spark | Resilient distributed data set caching using Spark SQL | Partitioning by year |
| Total record count | 1.9 minutes | 15 seconds | 5 seconds |
| Passenger Count | 1.9 minutes | 13 seconds | 5 seconds |
| Total Amount | 2.8 minutes | 12 seconds | 6 seconds |
The results using Spark 2.0.0 preview release are most impressive.
For an in-depth look at the entire process, download our white paper.
Be the first to get updates