 Arunachalam Kandasamy Raja
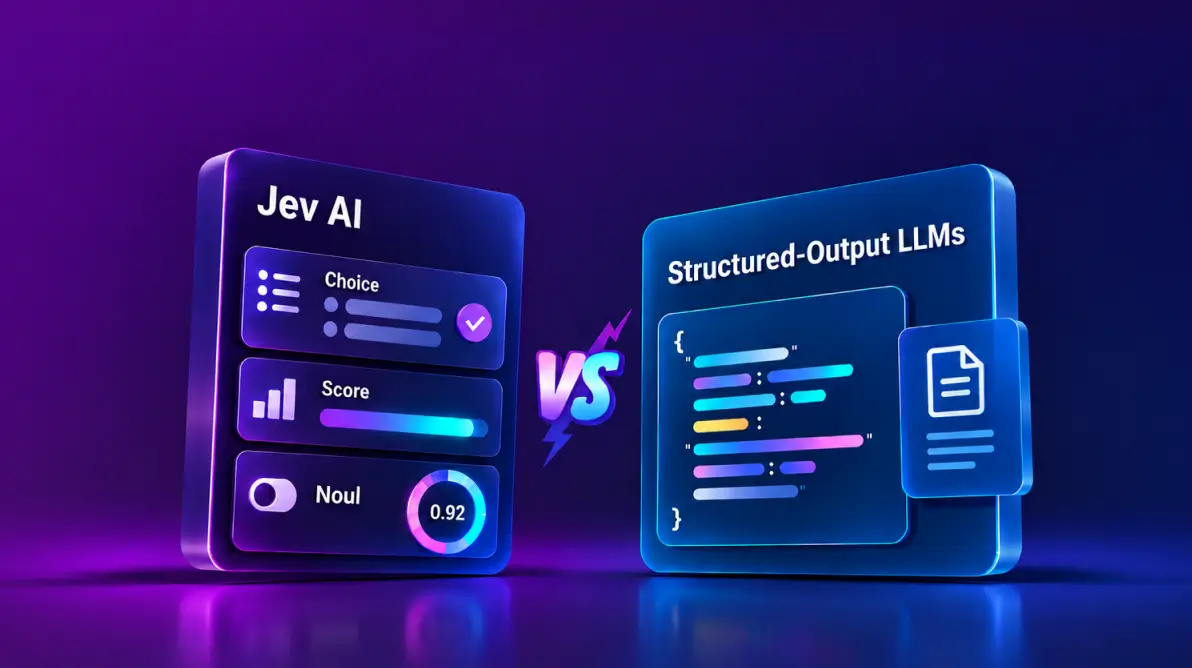
TL;DR: Choosing between Jev AI and structured-output LLMs? It comes down to the task. Jev AI is great for quick decisions like categorizing, scoring, and routing, while structured-output LLMs handle tasks like extracting data, explaining results, and planning. Need both? You can combine them. Just remember: well-formatted output doesn’t always mean a correct decision. Test with your own data, and keep critical business rules in your application code.
Imagine a customer submits a support ticket saying they’re locked out of their account. Your AI model reads the ticket, returns perfectly formatted JSON, and routes the issue to the billing team instead of security.
Here’s an example response:
{
  "route": "billing",
  "priority": "low",
  "requires_human_review": false
}
The format is flawless. The decision is wrong.
That’s the problem in a nutshell. A model can return an answer that passes every structural check and still misunderstand the actual situation.
There are two approaches worth considering:
-
Structured-output LLMs: Constrain a model’s response to a format or schema you define.
-
Typed decision models like Jev AI: Return clear, bounded answers, such as a category, score, or yes/no probability.
In this guide, we’ll explore how each approach works, when to use it, how to test it, and where document data fits into the process.
A note on sources: Information about Jev AI and its maker, TypeSafe, in this article is based on their published documentation at the time of writing. Treat any performance, speed, cost, or capability claims as the provider’s reported figures until you’ve tested them with your own data. Always check the official TypeSafe Quick Start and API Reference for the latest request and response formats before implementation.
How we used to handle messy model output
For a long time, working with LLM output involved the same repetitive process: write detailed prompt instructions, parse the JSON, validate it, and retry whenever the response broke the expected format.
Then providers such as OpenAI and Anthropic introduced structured-output features. These allow developers to constrain a model’s response to a predefined schema. That’s a significant improvement, although the exact rules and capabilities vary by provider and API version.
Structured output helps address several common problems:
-
Required fields must be present.
-
Field types remain consistent.
-
Dropdown-style values stay within the allowed options.
-
Tool inputs match their definitions.
-
Your application code spends less time handling malformed JSON.
However, structured output doesn’t guarantee that the answer is correct. It controls the shape of the response, not the accuracy of the model’s judgment.
Structured outputs in 60 seconds
A structured-output LLM is a regular text-generating model configured to return its response in a format you define.
For example, you might define a TypeScript type for assessing support tickets:
type TicketAssessment = {
  summary: string;
  route: "billing" | "technical" | "account";
  urgency: number;
  explanation: string;
};
This approach is useful when a task requires more than a simple decision, such as:
-
Extracting multiple fields from a contract.
-
Writing an explanation for a human reviewer.
-
Summarizing an incident before categorizing it.
-
Creating a step-by-step plan.
-
Converting a conversation into tool inputs.
-
Returning supporting quotes or evidence alongside an answer.
The biggest advantage is flexibility. One model can interpret instructions, summarize information, generate text, call tools, and populate structured data.
The limitation is that matching a schema doesn’t prove the content is accurate or that the model’s confidence is reliable. For example, a field such as “confidence”: 0.93 is just a number generated by the model until you’ve tested how often its predictions are actually correct.
So, what is Jev AI?
Jev AI is TypeSafe’s flagship System One model. The name reflects its focus: quick, bounded judgments rather than lengthy reasoning or essay writing.
Instead of returning paragraphs, Jev AI provides clear, typed answers.
You send Jev two things:
-
State: The information it needs to evaluate, such as a support ticket, transaction, policy, or application data.
-
Typed questions: The specific decisions you want it to make.
Jev AI returns answers through three main building blocks:
-
Choice: Selects one option from a list you define and provides the probability for each option, along with a confidence value.
-
Score: Evaluates a situation against levels you define and returns a score, the probability for each level, and a confidence value.
-
Noul: Answers a single yes/no question and provides the probability that the answer is yes.
There’s also an experimental Box building block for image-related tasks. However, TypeSafe identifies it as a feature that is still changing, so avoid depending on it for critical workflows until its behavior is established. Always confirm these definitions in the current documentation.
The key is to break a large decision into smaller, specific questions.
Instead of asking a model, “Look at this ticket and decide what to do,” you could ask:
-
Choice: Which team should handle this ticket?
-
Score: How seriously is the customer affected?
-
Noul: Does this situation require immediate human review?
Your application code then uses those answers alongside business rules and authoritative account data to make the final decision.
Jev AI vs. Structured-Output LLMs: A side-by-side comparison
Capabilities vary by provider, model, and version. Use this comparison as a general guide rather than a guarantee about every available tool.
| Comparison | Jev AI | Structured-output LLM |
|---|---|---|
| What do you send? | State and typed questions. | A prompt and a schema or tool definition. |
| What do you get back? | Choice, Score, and Noul responses. | Objects, arrays, or tool inputs that match your schema. |
| Can it generate prose? | Not really. That’s not its primary purpose. | Yes, when the schema allows text fields. |
| What confidence information is available? | Choice and Score provide probabilities and confidence. Noul provides a yes probability. | Some models provide confidence-like values, but you must test whether they’re trustworthy. |
| How is the output controlled? | Constrained to the selected building block. | Some APIs enforce the schema. Available features vary. |
| Where should business rules live? | In your application code. | In your application code, not buried in prompts. |
| What is it best suited for? | Sorting, scoring, routing, and gating. | Extracting, explaining, planning, and generating. |
| What’s the biggest limitation? | A valid answer can still be wrong. | A valid answer can still be wrong. |
Understanding Jev AI’s confidence values
For Choice and Score, Jev AI provides a confidence value between 0 and 1. This value reflects how clearly the probabilities point toward one outcome.
If one option clearly stands out, confidence is high. If the probabilities are close, confidence is low.
Noul doesn’t provide a separate confidence field. Its output is the probability that the yes/no statement is true.
In either case, test these values against your own labeled data before relying on them.
A bounded answer can still be wrong
Suppose a Choice question allows only four options: billing, technical, security, and other.
Jev AI can’t return a fifth option outside that list. However, it can still select billing for a ticket that describes a security problem.
Staying within the allowed options doesn’t mean the selected option is correct.
Which one should you choose?
Here’s a simple way to decide:
-
Need text generation, data extraction, or planning? Use a structured-output LLM.
-
Need a clear, bounded decision? Try Jev AI.
-
Need to generate data and make decisions about it? Use both together.
-
Have a non-negotiable rule? Keep it in application code, not in a model.
First, where does the data come from?
Here’s something that’s easy to overlook: both approaches depend on the quality of the data you provide.
Feed a model incomplete or incorrect information, and you can get confident, well-formatted but equally incorrect results.
In most business applications, that information starts in documents. These might include PDFs, Word files, Excel spreadsheets, scanned images, or email attachments.
Converting these files into clean, usable data is a document-processing task. That’s where the Syncfusion® Document SDK can help:
-
PDF Library: Extract text and form data from PDF documents.
-
Word Library (DocIO): Extract clauses, headings, and fields from Word documents.
-
Excel Library (XlsIO): Extract line items and totals from spreadsheets.
-
OCR processor: Convert scanned or image-based documents into readable text.
A typical document-to-AI pipeline
A real-world pipeline might look like this:
-
Extract document content: Use Syncfusion® Document SDK to retrieve content from the source file without involving an AI model.
-
Structure the data: Use a structured-output LLM to organize the extracted content into fields such as names, dates, and line items.
-
Make bounded decisions: Use Jev AI to answer specific questions about the structured data, such as which queue should handle it, how serious a mismatch is, or whether it should be escalated.
-
Apply application rules: Use your code to enforce non-negotiable rules and validate decisions against authoritative data.
The benefit is straightforward: reliable document processing gives your AI layer cleaner input. This also helps ensure your tests measure the model’s performance rather than errors introduced during document parsing.
Explore the Syncfusion Document SDK documentation and samples to find the formats and APIs that fit your platform.
A smart way to connect everything
The golden rule is simple: keep model judgments separate from hard rules.
Security, authentication, permissions, compliance, and validation rules should run independently. A model must never be allowed to override them.
Here’s the workflow:
-
Start with a document source, such as a PDF, Word document, Excel spreadsheet, or scanned file.
-
Use the Syncfusion® Document SDK to extract the content and convert it into application data (state).
-
Send that state through two separate paths:
-
Path 1 – Hard rules: Apply security, authentication, and compliance checks to determine the enforced outcome.
-
Path 2 – Model judgments: Use Jev AI or a structured-output LLM, then validate the results against your checks and risk thresholds.
-
Automate the action when the result is sufficiently reliable and low risk.
-
Send uncertain or high-risk results to a human reviewer.
Example: Enforcing a Security Policy Before Routing a Ticket
The following example illustrates how application code can enforce a mandatory security rule before using model-generated decisions.
Important: This is a conceptual example, not production-ready SDK code. It is not a real Jev integration, and TicketDecision is not a real Jev type. A production implementation would also need to handle authentication errors, timeouts, rate limits, and unexpected responses. Refer to the official TypeSafe documentation for the actual request and response formats.
type Department = "billing" | "technical" | "security" | "other";

type TicketState = {
  suspectedAccountCompromise: boolean;
};

type TicketDecision = {
  department?: { choice?: unknown; confidence?: number };
  immediateEscalation?: { noul?: number };
  impact?: { score?: number; confidence?: number };
};

type NextStep =
  | { action: "security_review"; reason: "mandatory_security_policy" }
  | { action: "human_review"; reason: string }
  | { action: "auto_route"; team: Department };

const departments = ["billing", "technical", "security", "other"] as const;

function isDepartment(value: unknown): value is Department {
  return (
    typeof value === "string" &&
    (departments as readonly string[]).includes(value)
  );
}

const inUnitInterval = (value: unknown): value is number =>
  typeof value === "number" && Number.isFinite(value) && value >= 0 && value <= 1;

const inImpactRange = (value: unknown): value is number =>
  typeof value === "number" && Number.isFinite(value) && value >= 0 && value <= 3;

function chooseNextStep(state: TicketState, result: TicketDecision): NextStep {
  // Hard rule always wins, no matter what the model says.
  if (state.suspectedAccountCompromise) {
    return { action: "security_review", reason: "mandatory_security_policy" };
  }

  const department = result.department;
  const immediateEscalationProbability = result.immediateEscalation?.noul;
  const impact = result.impact;

  const valid =
    department !== undefined &&
    isDepartment(department.choice) &&
    inUnitInterval(department.confidence) &&
    inUnitInterval(immediateEscalationProbability) &&
    impact !== undefined &&
    inImpactRange(impact.score) &&
    inUnitInterval(impact.confidence);

  if (!valid) {
    return { action: "human_review", reason: "invalid_or_missing_model_output" };
  }

  const sensitiveRoute = department.choice === "security" || impact.score >= 2.5;
  const uncertain = department.confidence < 0.85 || impact.confidence < 0.8;

  if (sensitiveRoute || uncertain || immediateEscalationProbability > 0.75) {
    return { action: "human_review", reason: "risk_or_uncertainty_threshold" };
  }

  return { action: "auto_route", team: department.choice };
}
Understanding the impact scale
The example uses the following impact levels:
-
0: Nobody notices.
-
1: Minor issue, with a workaround available.
-
2: Something important is broken for one or more users.
-
3: A major outage, security exposure, or similar issue.
The thresholds in the example, 2.5, 0.85, 0.80, and 0.75, are illustrative values, not recommended defaults.
Choose your own thresholds using real labeled data. Consider the cost of an incorrect decision, your team’s review capacity, and how easily an action can be reversed.
The Noul question in this example is: “Does this ticket need a human right away?”
Define exactly what that question means before allowing its probability to influence an application action.
Where can you use these approaches?
Here are three practical scenarios where Jev AI and structured-output LLMs can work together.
1. Support and incident triage
Jev AI is useful when you repeatedly need to route support tickets to teams, score their impact, or identify possible escalations.
A structured-output LLM is a better fit when you also need to summarize a ticket, extract reproduction steps, or draft a response.
Known account-compromise signals should always follow the mandatory security path. Jev AI can help assess less obvious cases, but it should never override that rule.
2. AI-Agent guardrails
Before an AI agent issues a refund, changes permissions, or deploys an application, a typed decision model can provide a risk signal.
However, authentication, permission checks, limits, and audit logging remain the responsibility of your application.
3. Document processing
Structured-output LLMs are generally better suited to extracting names, dates, clauses, and line items from documents. This can happen after a Syncfusion® Document SDK has already converted the source file into clean text.
Jev AI can then evaluate the extracted information and make bounded decisions. For example, it can assign a review queue, score the seriousness of a mismatch, or assess whether enough evidence exists to automate a step.
In this workflow, one model turns content into structured data, while the other makes bounded decisions about that data.
Both approaches still need validation against your actual records.
How to test it properly (don’t skip this)
Before using either approach in a real workflow, you need to understand how reliably it performs.
First, let’s clarify one important term: calibration.
Calibration measures whether a model’s confidence matches reality. For example, if a model says it is 90% confident across a group of predictions, it should be correct about 90% of the time for that group to be well calibrated.
If the confidence doesn’t match actual results, you shouldn’t rely on that number to make decisions.
Start with a labeled test set
Choose one workflow that is easy to reverse. Before connecting the model to a real action, build a labeled test set.
Include:
-
Normal, straightforward cases.
-
Ambiguous cases.
-
Cases with missing information.
-
Unusually worded or misleading cases.
-
Rare but high-impact scenarios.
Also, keep the following points in mind:
-
For Choice: Add an other or needs_review option unless your list of choices is genuinely complete.
-
For Score: Define each level using observable criteria.
-
For Noul: Ask one question at a time so the response remains clear.
A practical testing checklist
Once your test set is ready, follow these steps:
-
Ask domain experts to define the correct answers and resolve disagreements.
-
Build a confusion matrix to identify which categories are being mixed up.
-
Measure precision and recall for each category instead of relying only on overall accuracy.
-
Test calibration by grouping predictions and comparing their confidence with actual outcomes.
-
Set thresholds based on risk, review capacity, and the cost of mistakes.
-
Run the new approach in shadow mode, where it observes cases without taking action.
-
Track speed (P50, P95, and P99), cost per decision, escalation frequency, and changes in the input data over time.
A quick example: Measuring security recall
Suppose you test 100 confirmed security incidents.
The system correctly routes 92 incidents to security and misses eight. That gives you 92% recall for security on this test set.
That’s useful information, but it doesn’t tell you how often the system incorrectly routes non-security tickets to the security team.
To measure that, calculate precision using the false positives across your full test set. Then validate both precision and recall using fresh holdout data before moving to production.
Roll out gradually and monitor results
Once shadow testing produces acceptable results, roll out the workflow gradually. Define your rollback conditions before enabling live actions.
Consider rolling back if:
-
Security recall drops.
-
Confidence calibration changes significantly.
-
Human review volume increases unexpectedly.
-
Response times become too slow.
-
The cost of correcting mistakes becomes too high.
One more recommendation: pin the model version whenever possible.
If the provider uses a moving model label, record the label, date, questions, evaluation criteria, and test results. Repeat your tests whenever the provider changes the model or its behavior.
Finally, treat any speed or cost figures published by TypeSafe as provider-reported results until you reproduce them using your own data, traffic, and review process.
Still not sure? Follow this decision flow
Use these questions to choose the right approach:
-
Need generated text, data extraction, or variable-length output? Use a structured-output LLM.
-
Can the task be expressed as a choice, score, or yes/no question? Try a typed decision model like Jev AI.
-
Does the task fit neither approach? Rework it or handle it in plain application code.
-
Need to generate data and make decisions about it? Use both approaches together.
-
Is the requirement a non-negotiable rule involving security, authentication, or compliance? Enforce it in application code, never in a model.
Quick glossary
-
System One model: A model designed for fast, bounded decisions rather than deep reasoning.
-
Noul: A Jev AI building block that returns the probability that a yes/no statement is true.
-
Calibration: A measure of whether a model’s confidence matches how often it is correct.
-
Constrained decoding: A technique that constrains a model’s output to a defined structure.
-
Semantic correctness: Whether an answer is actually correct, rather than simply well-formatted.
Frequently Asked Questions
What can I feed Jev AI?
According to TypeSafe’s documentation, Jev AI accepts text in the form of a string, JSON object, or array of text values. It doesn’t directly accept audio or video.
Convert those inputs into text first. A document SDK can help process supported files, but you should still validate the converted content before relying on the resulting decision.
Can I use Jev AI for regulated decisions?
Jev AI can assist with regulated workflows, but a probability alone may not satisfy requirements involving explanations, fairness, or auditing.
Keep records of the input, questions, model version, probabilities, final outcome, and any human overrides. Obtain legal and compliance approval before automating high-impact decisions.
What if Jev AI needs information that isn’t in the data I sent?
A well-structured answer doesn’t prove that the input data is complete.
Retrieve authoritative information before making the decision, identify missing values clearly, and provide an unknown or human-review path wherever missing information could affect the outcome.
If I use Jev AI, do I still need structured-output LLMs?
Usually, yes.
Many real-world implementations use a structured-output LLM, together with a document SDK, to prepare the data. A typed decision model can then evaluate that data.
They work better as complementary tools than as competing alternatives.
Wrapping up
Think of Jev AI as a specialist for small, clearly defined decisions such as sorting, scoring, and routing. Structured-output LLMs are generalists that handle tasks such as extracting information, explaining results, planning, and generating text.
Many applications can benefit from using both. Keep non-negotiable rules in your application code, and use a reliable document-processing layer to provide clean input data.
Start with one workflow that you can easily reverse. Evaluate accuracy, precision and recall for each category, calibration, speed, escalation rate, and cost using real data.
Only after those results meet your requirements should you allow a model to influence a live action.
Where to go next
-
Review the current Jev AI building blocks and supported formats in the official TypeSafe Quick Start and API Reference.
-
Explore the Syncfusion Document SDK documentation to learn how to convert PDFs, Word documents, Excel spreadsheets, and scanned files into usable data for your AI workflows.
-
Try an extract-then-decide pipeline using one of your own documents.
-
Start a free Syncfusion trial and evaluate the Document SDKs in your application.
Be the first to get updates